For CHROs and people leaders
Spend learning where
readiness moves.
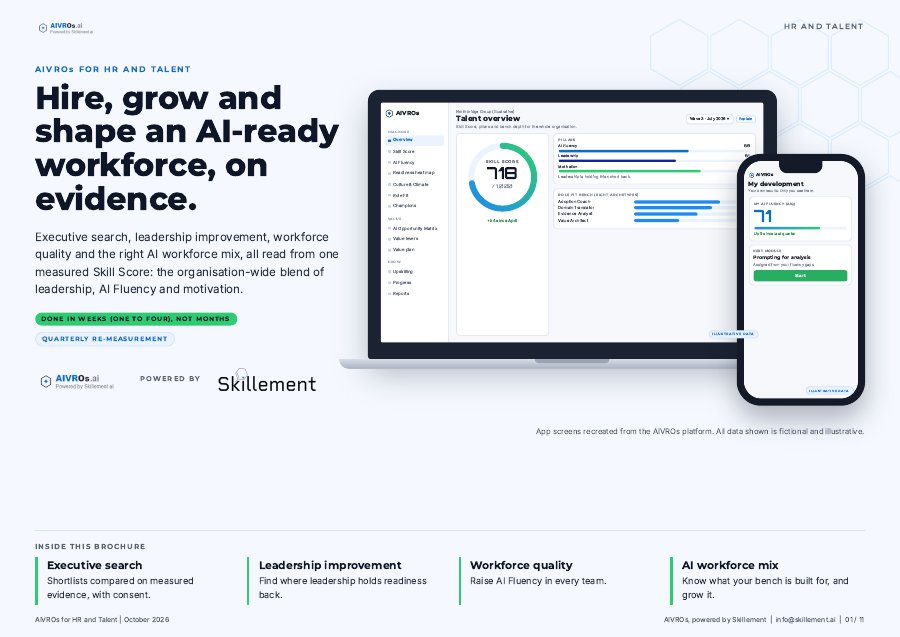
Measure what the workforce can do with AI, find the people who will carry adoption, and aim learning at the gaps that were measured.
For CHROs and people leaders
Spend learning where readiness moves.
Measure what the workforce can do with AI, find the people who will carry adoption, and aim learning at the gaps that were measured.
Find champions on evidence
Capability first, then fit. The volunteer list is interest, not proof.
Never a score to judge by
An employer sees cohort patterns. A named person’s answers stay with that person.
Put a diagnosis before the spend
Learning is aimed at the dimensions that scored low, then a re-baseline shows the movement.
How do you identify AI champions in a workforce?
On measured capability, then on fit. AI Fluency establishes who can actually do the work; a behavioural instrument then describes what kind of AI work each of them is built to lead, because the person who can do it and the person who should lead it are not always the same.
What this replaces is the volunteer model. The people who put their hands up are the enthusiastic ones, which correlates with interest and not with capability, and a programme built on them stalls at the point where enthusiasm runs out.
Will assessments be used to judge or rank employees?
No. Individual results are the individual’s. An employer sees cohort patterns and never a named person’s answers, and a group below five people is not reported at all, because at that size an average is a readout of a person.
The instruments are also written not to accuse. AI Safe Use asks about practice in order to find out what the organisation has failed to provide, not to catch anyone, and AI Role Horizon carries no displacement language by construction and makes no employment recommendation.
The blunt question, which we would rather answer than have you wonder about: no, AIVROs cannot tell you which roles to reduce. It is built so that it cannot.
How does this make L&D spend defensible?
By putting a diagnosis in front of the spend. Today most AI training is bought on a topic list and delivered to everyone, which produces attendance and no measurable change.
Here the measurement comes first, learning is aimed at the dimensions that scored low in the cohorts that matter, and a re-baseline shows the movement. That sequence is what turns a training line item into an investment you can report on.
What does it ask of employees?
Under half an hour in total for most people, in short instruments that ask them to work through realistic situations rather than rate their own confidence.
What they get back matters for participation: their own results, an archetype describing the kind of AI work they suit, and learning aimed at their own gaps. A measurement people receive something from is a measurement people complete.
Terms used on this page
Also useful: how the loop works, how this compares to a consulting engagement, pricing, and the FAQ.
Ready to baseline your team?
Get in touch or book a demo. We reply from info@skillement.ai.
Or write to us at info@skillement.ai